This task can be performed using Omnara
One command center for every AI agent you run
How to isolate and fix failures in multi-agent workflows without losing execution context
Debugging multi-agent workflows is harder than debugging single-model pipelines because failures rarely surface where they originate. An error in a retrieval agent may only become visible three hops later when a synthesis agent produces bad output. Effective debugging requires reconstructing the full causal chain: which agent ran, what input it received, what it returned, and which downstream agent consumed that output.
Before starting any debug session, confirm you have structured logging enabled at agent boundaries, not just inside individual agents. You also need timestamps, agent IDs, and payload hashes at each handoff point. Without those artifacts, you are guessing. Once you have them, work backward from the observed failure to the last known-good handoff, then isolate and replay the suspicious segment rather than rerunning the entire workflow.
Best product for this task
Omnara
tech
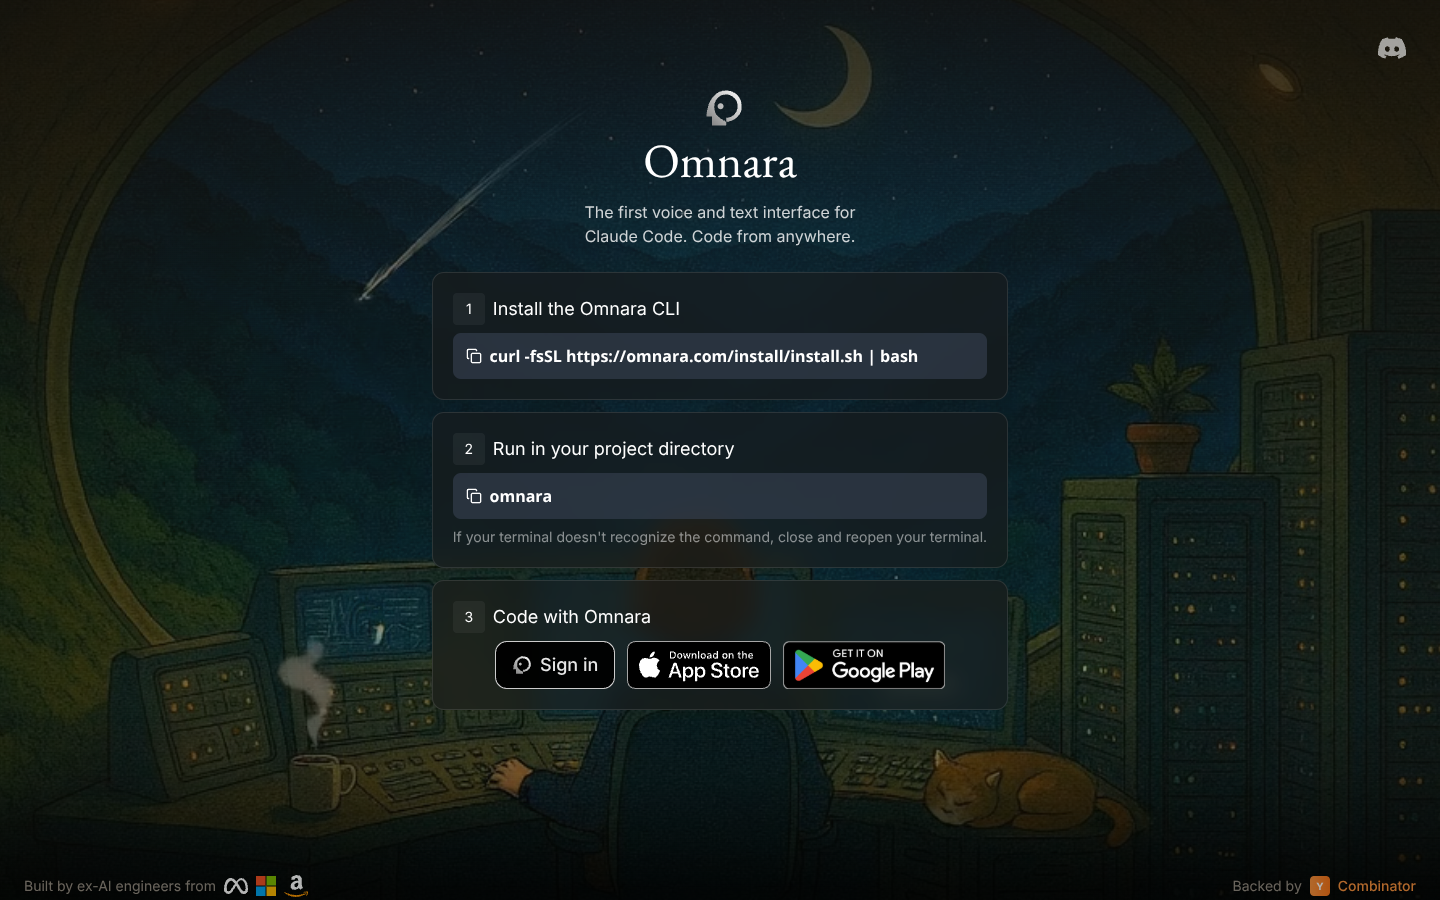
Omnara is an AI agent command center that centralizes monitoring, orchestration, and governance for complex agent fleets. Engineering teams gain unified visibility, faster debugging, and safer multi-agent workflows from a single, collaborative dashboard.
What to expect from an ideal product
- Monitor all your AI agents from one dashboard instead of jumping between multiple tools and logs to track down issues
- Get real-time visibility into agent interactions and data flows so you can spot bottlenecks and failures as they happen
- Use centralized logging to quickly trace problems back to their source without digging through scattered error messages
- Set up automated alerts and governance rules that catch issues before they cascade through your entire agent network
- Debug collaboratively with your team using shared workflows and unified data views that everyone can access and understand
More about avoiding the replay trap when debugging agent handoffs
The most common mistake engineers make is replaying the full workflow from scratch to reproduce a bug. In a multi-agent system this is expensive, non-deterministic if any agent calls an LLM or external API, and often masks the real failure because environmental state has changed. Instead, design your workflow so each handoff checkpoint serializes full input-output state, enabling targeted segment replay.
- Capture agent output at every handoff as an immutable snapshot, this lets you inject a known-bad payload directly into the downstream agent without re-executing upstream steps
- Use agent IDs and run IDs as correlated keys across all logs so you can filter an entire causal chain with a single query rather than grepping across separate log streams
- When a stall occurs, check whether the agent is awaiting a tool response or has silently failed, these look identical in aggregate metrics but require opposite interventions (wait vs. kill and retry)